Search
Results for “model”
33 models, tools and templates match.
Showing 1–24 of 33
**COMING SOON.** Show the same apparel mockup on a model in multiple poses — front, side, back, walking, sitting — from one design.
Nano Banana 2.1 is Google's October 2026 refresh of its fast Flash-tier image model: one model for text-to-image, conversational editing and fusion of up to 14 reference images. It reasons through the prompt before it renders, so lighting briefs, exact wording and structured layouts such as infographics land more reliably than on Nano Banana 2, for about half the credits at 1K and 2K.

Nano Banana Pro is Google's state-of-the-art image generation and editing model — the strongest reasoning tier in the Nano Banana line. Multi-image fusion up to 14 references, output up to 4K, configurable safety filtering, and an optional fallback model for batch throughput.
FLUX 3 is Black Forest Labs' flagship image model: one model that generates from text, edits photos and composes new scenes from up to ten reference images. Before it draws, it can research your prompt with web and image search, so real places, products and events come out right. Exact typography, element-level layout control and output up to 4K (16 MP) make it a natural fit for print-ready posters, apparel graphics and ad creatives.

Try-On v1 is the platform's first-generation virtual try-on app — pass a design and an optional model reference, and the app renders the design on apparel with a default pose. The newer Try-On Guided (model_id=44) is the supported successor; this v1 endpoint stays for back-compat with older catalogue flows.
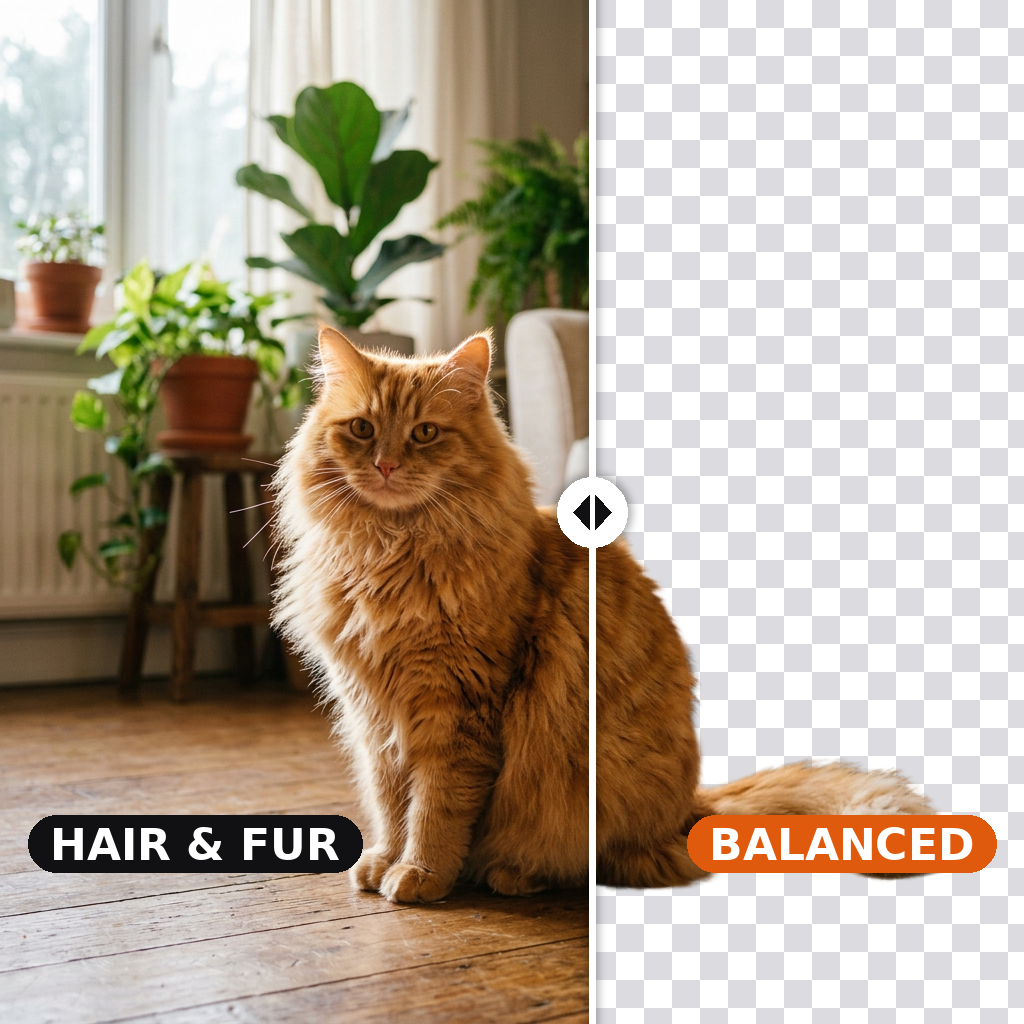
Our balanced background remover. Drop in a single image — product photo, portrait, AI-generated render, illustration — and the model returns a clean alpha-channel cutout, tuned to survive fine edges like hair, fur, fabric folds and glass.
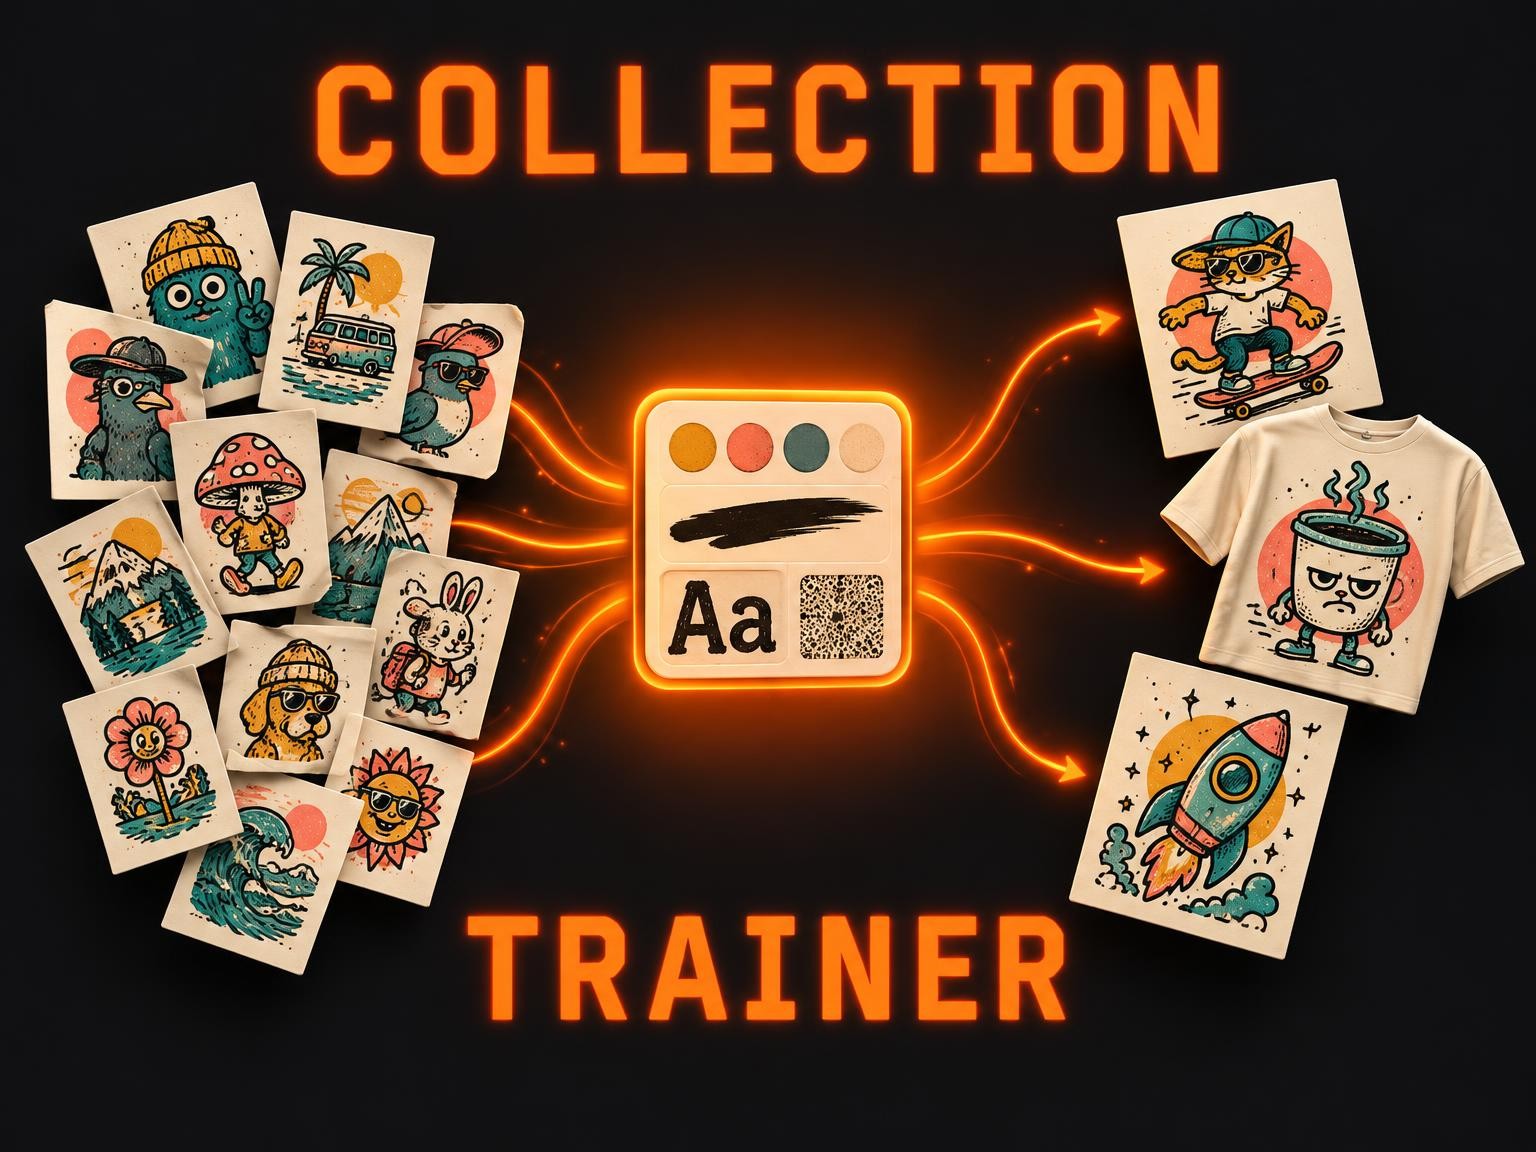
Train a reusable style pack from 3–30 of your designs. Upload a ZIP and get a collection model that turns any idea, or a photo, into new designs in that same style, ready for print.
Nano Banana 2 is Google's fast image generation and editing model — text-to-image plus conversational editing, multi-image fusion (up to 14 references) and character consistency. Output at 1K, 2K or 4K. Optional Google Search and Image Search grounding pull current real-world references into the generation.
FLUX.2 [klein] 9B is the flagship of Black Forest Labs' compact FLUX.2 [klein] line: a 9-billion-parameter model distilled to just four sampling steps, so most images come back in a few seconds, from 2 credits. It generates from text and edits or combines up to five reference images in the same run, which makes it the cheapest way in our catalogue to explore ideas, draft designs and iterate on variations before you commit to a final render.
Nano Banana 2 Edit Fast is the fast-tier image-editing endpoint from Google's Nano Banana 2 line. Pass one to fourteen reference images plus a written instruction and the model rewrites them — at 2K or 4K output, with an optional web-search pass that grounds the edit in real-time context.
Wan 2.7 Image is Alibaba's standard-tier image model — text-to-image **and** image edit in one endpoint, with output up to 2K, optional thinking mode, and image-set mode for generating coherent variant grids from a single prompt. Same price as the Pro tier; use Pro when you need 4K.
Krea 3 is Krea's fast, edit-first image model: describe a change in plain language and it applies it in seconds while keeping products, logos and characters recognisable, or leave out the images and it generates from text. Combine up to 8 images, switch to high thinking to plan multi-step edits, and use the experimental regional edit to change one detail while the rest of the picture stays untouched.
Grok Imagine Image 2 is xAI's second-generation image model, released in August 2026 and ranked second on Arena's text-to-image and image-editing leaderboards at launch. It plans typography and layout the way a designer would, moves between photography and illustration with ease, and edits a single photo from a plain-language instruction. Every image costs a flat 4 credits, so 2K at full quality is the default, not an upgrade.
Ideogram 4.5 is Ideogram's September 2026 model for generating and editing images in one place, built on the lettering the brand is known for: slogans, logos, posters and labels that read correctly. Its edge is precise editing. Rewrite or translate a line of text, recolour a product or repaint a masked area, and the rest of the image comes back untouched, ideal for print-on-demand designs that need one more fix rather than a full redraw.
**COMING SOON.** Add crisp, editable-quality text to any design: place a slogan, name or date on top of an artwork with the right font, size, curve and colour, without the garbled lettering image models sometimes produce.
Wan 3.0 Video Edit rewrites an existing clip from a plain-language instruction — remove an object, change an outfit or a character's age, restyle or relight the whole shot, or even change what someone says. It is the editing mode of Alibaba's unified Wan 3.0 model, keeps the original framing and length, and can pull new looks from up to ten reference images.
Seedance 2.5 Text to Video is ByteDance's next-generation video model, turning a written brief into a single continuous take of up to 30 seconds — with dialogue, effects and ambience generated in the same pass. It renders up to native 4K and, when you need it, follows up to 30 reference images plus video and audio references for characters, products and motion.
Wan 3.0 Reference to Video turns the material you already have — product shots, character photos, a sample clip, a voice or a jingle — into a new video of up to 30 seconds with sound generated in the same pass. It is the standard tier of Alibaba's unified Wan 3.0 model and takes up to ten images, five video clips and five audio clips per shot, at 480p, 720p or 1080p.
MiniMax H3 Image Edit is the image-editing mode of MiniMax H3 — also known as Hailuo 3.0 — the open-weights multimodal model MiniMax launched in July 2026. Feed it up to nine reference images and a written instruction and it re-renders the subject into a new scene, outfit or style while holding on to their identity, at 1K or 2K.
Seedance 2.0 Pro is ByteDance's flagship text-to-video model — strong prompt adherence, natural motion, and optional multimodal references (images, videos, audio) to lock identity, style, and rhythm. This is the native ByteDance ModelArk endpoint; the WaveSpeed-routed siblings stay in the catalogue for users that already point at them.
Wan 2.7 Video Edit is Alibaba's video-to-video editor — drop in a 2-10 second clip plus a written instruction ("swap the weather", "restyle as claymation", "replace the backdrop") and the model rewrites the clip while preserving the camera move, framing and subject motion of the original.
Wan 2.7 Image Pro is Alibaba's flagship image model — text-to-image **and** image edit in one endpoint, with **4K output** support, optional thinking mode for higher-quality reasoning, and image-set mode for generating coherent variant grids from a single prompt.
Pruna Video Avatar is the fastest talking-avatar / lip-sync model on the market — drop in a portrait photo plus either an audio clip or a written script, and get back a video of the subject speaking with synchronised lip movement, in 30 voices and 10 languages.
Pruna's image upscaler — the fastest on the market today, with sub-second inference and output up to 128 megapixels. Pick a target megapixel count or a per-side scaling factor, optionally boost details or realism, and ship hero-resolution assets without the diffusion-model cost.